Architecture & Code
Architecture diagrams and implementation notes behind four of the pipelines from the Projects page. Code snippets are illustrative reconstructions — originals are proprietary.
Featured Dashboard
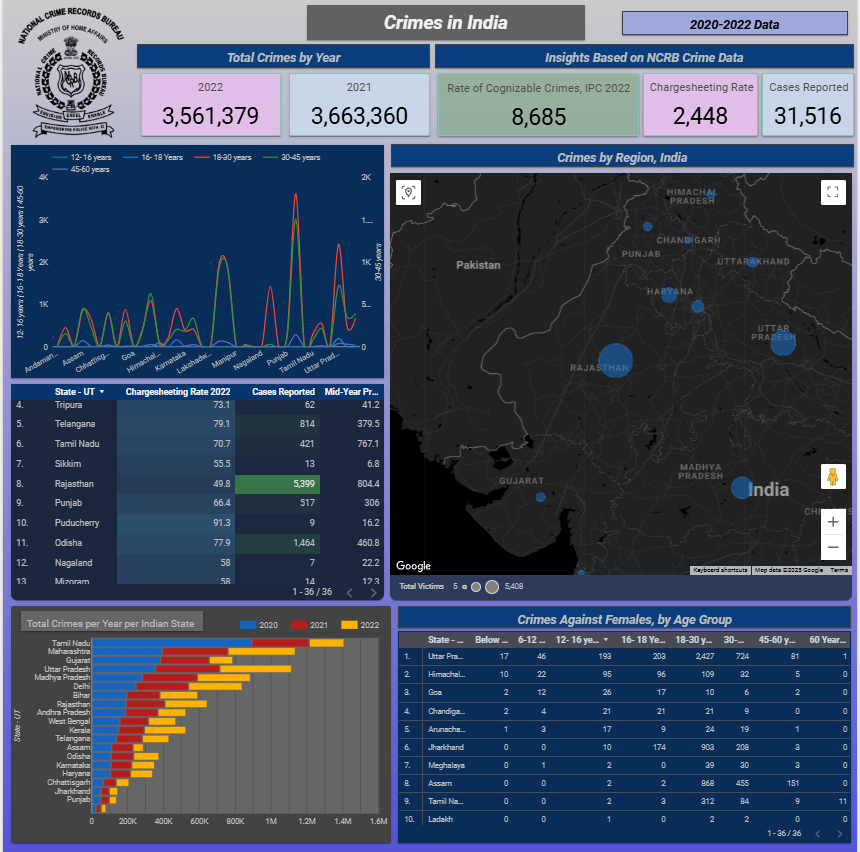
Crimes in India — BI Report
Built on NCRB data, broken down by region and age group. Feeds directly from BigQuery via an automated GCP Python pipeline — no manual refresh.
- · Sources directly from BigQuery
- · State & age-group breakdowns
- · Regional crime density geo map
Code & Architecture
AI / LLM PII Redaction Logic
Hybrid rule-based + LLM verification pass that scrubs PII before content ships (Project 1).
# pii_redaction.py — hybrid rule + LLM pass
import re
from langchain.chat_models import ChatOpenAI

RULES = [
    (re.compile(r"\b\d{10}\b"), "[PHONE]"),
    (re.compile(r"[\w.+-]+@[\w-]+\.[\w.-]+"), "[EMAIL]"),
]
llm = ChatOpenAI(model="gpt-4o-mini", temperature=0)

def rule_pass(text: str) -> str:
    for pattern, tag in RULES:
        text = pattern.sub(tag, text)
    return text

def llm_verify(text: str) -> str:
    # catches names, addresses, context-only PII the rules miss
    prompt = f"Redact remaining PII in:\n{text}"
    return llm.invoke(prompt).content

def redact(raw: str) -> str:
    return llm_verify(rule_pass(raw))  # same input → same output
← swipe to see the full pipeline →
ETL Transformation Logic (Python)
Cleaning and refining UK government datasets before loading into PostgreSQL (Project 4).
# Standardise currency and date formats
def clean_and_transform(df):
    df = df.dropna(subset='record_id')
    df['amount'] = (df['amount']
        .str.replace('£', '').str.replace(',', '').astype(float))
    for col in ['issue_date', 'expiry_date']:
        df[col] = pd.to_datetime(df[col], errors='coerce')
    df['duration_days'] = (
        df['expiry_date'] - df['issue_date']).dt.days
    return df
← swipe to see the full pipeline →
FastAPI Endpoint — GCP Cloud Run
Serving clean BigQuery data to PowerApps and Power Automate behind the HCLTech automation tool (Project 2).
# main.py deployed to GCP Cloud Run
from fastapi import FastAPI, HTTPException
from typing import List, Dict

app = FastAPI()
bq = get_bigquery_client()

@app.get("/api/v1/client_data", response_model=List[Dict])
async def get_client_data():
    try:
        df = bq.query(
            "SELECT * FROM client_dataset.latest_snapshot"
        ).to_dataframe()
        return df.to_dict('records')
    except Exception as e:
        raise HTTPException(status_code=500, detail=str(e))
← swipe to see the full pipeline →
Web Scraping & Sentiment Scoring
Scraping and scoring sentiment across 200+ websites on an automated schedule (Project 5).
# sentiment_pipeline.py
from bs4 import BeautifulSoup
import requests

def fetch_text(url: str) -> str:
    soup = BeautifulSoup(
        requests.get(url, timeout=10).content, "html.parser"
    )
    return " ".join(p.get_text() for p in soup.find_all("p"))

def score_sentiment(text: str) -> float:
    pos = {"good", "strong", "growth"}
    neg = {"bad",  "weak",   "decline"}
    w   = text.lower().split()
    s   = sum(x in pos for x in w) - sum(x in neg for x in w)
    return s / max(len(w), 1)
← swipe to see the full pipeline →